
Best Local LLM for 16GB in 2026: RTX 5060 Ti, 4060 Ti and Mac mini M4 (Coding First)
gpt-oss-20b and Gemma 4 26B A4B lead on 16GB NVIDIA cards, while a 16GB Mac mini M4 is better served by Qwen3.5-9B. File sizes, context limits and VRAM math.
Latest post · Research
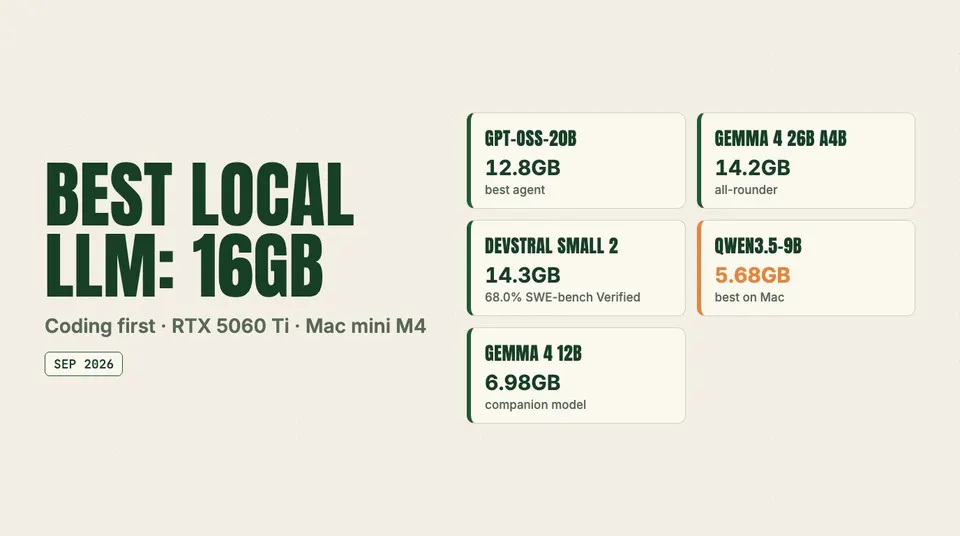
gpt-oss-20b and Gemma 4 26B A4B lead on 16GB NVIDIA cards, while a 16GB Mac mini M4 is better served by Qwen3.5-9B. File sizes, context limits and VRAM math.
 ChatGPT Pro $100 vs $200: 5× vs 20× Usage Explained (2026)ChatGPT Pro $100 vs $200 explained: same Pro features, 5× vs 20× usage vs Plus. Compare rate limits, Codex headroom, and which tier fits you.
 GLM Coding Plan Pricing 2026: Z.ai Lite vs Pro vs Max ExplainedConflating the subscription with the metered API produces Insufficient Balance errors, surprise charges, or a hard stop with no fallback mid-task.
 ChatGPT Pro 5x vs 20x for Codex Coding: Which Tier Actually Fits Agentic WorkChatGPT Pro 5x vs 20x for Codex: compare rate limits, token burn, and when Plus + API or $100/$200 Pro fits agentic coding, monorepos, and parallel agents.
 Xiaomi MiMo Token Plan Pricing: 2026 Tier Guide for Coding AgentsMiMo-V2.6 lands on the same four credit tiers at unchanged prices and burn ratios, while mimo-v2.5 goes offline on 21 October 2026 — and a per-seat Team Edition now exists.
gpt-oss-20b and Gemma 4 26B A4B lead on 16GB NVIDIA cards, while a 16GB Mac mini M4 is better served by Qwen3.5-9B. File sizes, context limits and VRAM math.

Price per GB, memory bandwidth, prefill vs decode on gpt-oss-120b, clustering and software stacks: which unified-memory desktop fits your local LLM work.

Copilot now bills in AI credits at $0.01 each. Here is what Pro's 1,500 and Pro+'s 7,000 credits buy per model, and when Pro+ beats Claude or Cursor.

Gemini CLI is gone for consumer plans. We compare Claude Code, Codex CLI, Google's agy and OpenCode on price, models, license, sandboxing and MCP.

All three now sell a 5x tier at $100 and a 20x tier at $200. We compare coding agents, limits, deep-reasoning modes and bundles, then pick by persona.

Opus 5.5 lists at $4/$20, Astra and Fable 5.1 at $10/$50. We compare cost per completed task, sourced benchmarks, speed, context and caching.

Opus 5.5 is now Claude Code's default on Pro. What a $20 plan's 5-hour window really covers, where it runs dry, and when Max 5x or 20x pays off.

How OpenClaw and Nous Research's Hermes Agent compare on architecture and local models, plus the major 2026 CVEs and a hardening checklist for both.