Laguna S 2.1 Coding Benchmark Performance: How Efficient Open Models Are Reshaping Enterprise AI
AK
Alex Kim Threat intelligence editor · Updated Jul 22, 2026, 2:36 PM EDT
The open-weight MoE model targets teams squeezed between frontier API costs, inference latency and data-residency rules that rule out hosted inference.
SAN FRANCISCO — Software engineering teams face a growing dilemma: relying on cloud-hosted frontier artificial intelligence models offers high capability but incurs steep API costs, latency bottlenecks, and strict data privacy constraints. That compromise shifted significantly with the release of Laguna S 2.1, an open-weight Mixture-of-Experts (MoE) coding model designed to deliver strong agentic performance within a fraction of the hardware footprint of massive cloud models.
Developed by artificial intelligence laboratory Poolside, Laguna S 2.1 features a total parameter count of 118 billion, yet activates only approximately 8 billion parameters per token during inference (~6.8% active). Released under the permissive OpenMDW-1.1 license, the model outscored open-weight competitors up to 14 times its total parameter size on several benchmark suites at launch, while ranking 11th overall on the Terminal-Bench 2.1 leaderboard Poolside published alongside it.
This article has been corrected. Two figures in the original version — a pair of local-inference throughput numbers and a claim about DeepSWE performance — were not supported by any published source. The correction note at the end of this article sets out what changed.
Benchmark Deep-Dive: Parameter Efficiency vs. Frontier Scale
The primary metric of interest for software architects is how a model with 8 billion active parameters competes against trillion-parameter deployments. In standardized evaluations, Laguna S 2.1 achieved notable scores across key software engineering and shell execution benchmarks, particularly when operating in its extended reasoning mode.
On Terminal-Bench 2.1, which measures multi-step command-line problem-solving, Laguna S 2.1 posted a score of 70.2, placing it 11th on the leaderboard Poolside compiled at launch. That put it ahead of the 1.6-trillion-parameter DeepSeek-V4-Pro-Max (64.0), the 975-billion-parameter Inkling (63.8) and the 550-billion-parameter Nemotron 3 Ultra (56.4), but behind Tencent's 295-billion-parameter Hy3 (71.7) and every frontier closed model on the board. On SWE-Bench Multilingual, its 78.5% topped Poolside's own published comparison set, edging Qwen 3.7 Max (78.3%); it was not the top of the public leaderboard, which Anthropic's Claude Mythos Preview leads at 87.3%. On DeepSWE v1.1, testing deep code comprehension and bug resolution, it scored 40.4% with reasoning enabled — well ahead of DeepSeek-V4-Pro-Max (9.0), and behind the 753-billion-parameter GLM-5.2 (44.0) in Poolside's own launch table.
Benchmark Suite
Laguna S 2.1 (118B-A8B)
DeepSeek-V4-Pro-Max (1.6T)
Inkling (975B)
Nemotron 3 Ultra (550B)
Kimi K3 (2.8T)
Claude Fable 5 (Closed)
Terminal-Bench 2.1
70.2
64.0
63.8
56.4
88.3
88.0
SWE-Bench Multilingual
78.5
76.2
—
67.7
—
—
SWE-Bench Pro (Public)
59.4
55.4
54.3
—
—
80.3
DeepSWE v1.1
40.4
9.0
—
—
69.0
70.0
SWE Atlas (Codebase Q&A)
46.2
27.2
—
—
—
—
Toolathlon Verified
49.7
55.9
45.5
34.3
—
—
Those are Poolside's launch-day figures, published 21 July 2026, and should be read as vendor numbers. Independent boards have since re-run several of the same models on their own harnesses and report different results — llm-stats, for example, now lists Claude Fable 5 at 84.3 on Terminal-Bench 2.1 rather than 88.0.
Almost two months on, the public standings look materially different:
Public leaderboard (13 September 2026)
Laguna S 2.1
Position
Current leader
Terminal-Bench 2.1
70.2
25th of 39
DeepSeek-V4.1-Flash (90.6)
DeepSWE v1.1
40.4
28th of 32
Muse Spark 1.3 (75.4)
SWE-Bench Pro (Public)
59.4
24th
Claude Fable 5.1 (81.2)
SWE-Bench Multilingual
78.5
outside the top tier
Claude Mythos Preview (87.3)
Two caveats apply to all of these numbers. Terminal-Bench 2.1 has been superseded twice, by 3.0 and then by 4.0 in August 2026; the maintainers describe the changes as breaking and state that trials must be re-run, so 2.1 and 4.0 scores are not comparable. Laguna S 2.1 has no published Terminal-Bench 4.0 result. Benchmark methodologies also vary across implementations: vendor evaluations on DeepSWE utilized custom agent harnesses, training runs required explicit filtering to prevent models from inspecting original pull-request patches online, and Poolside raised evaluation timeouts to five hours for Terminal-Bench 2.1, SWE-Bench Pro and SWE-Bench Multilingual, and six hours for DeepSWE v1.1.
Top-tier closed models retain a definitive edge on complex, high-reasoning tasks, and that frontier has moved since July. Claude Mythos 5.1 and GPT-6 Astra lead Terminal-Bench 4.0; Claude Fable 5.1 leads SWE-Bench Pro at 81.2%; Meta's closed-weight Muse Spark 1.3, released 3 September 2026, leads DeepSWE v1.1 at 75.4%.
More consequential for Laguna's own argument is what has happened on the open-weight side. DeepSeek released DeepSeek-V4.1-Flash on 10 September 2026 under the MIT license: 552 billion total parameters activating roughly 8 billion per token on input — the same active-parameter budget as Laguna S 2.1 — and it now sits first on the Terminal-Bench 2.1 board at 90.6 and second on DeepSWE v1.1 at 74.2. Z.ai's GLM-5.3-Flash (320B total, 18B active, MIT, 25 August 2026) scores 84.3 and 63.4 on the same two boards. Alibaba's Qwen3.8-27B, a dense 27.8-billion-parameter Apache-2.0 model released 14 August 2026, scores 73.0 on Terminal-Bench 2.1 and 61.7 on SWE-Bench Pro at less than a quarter of Laguna's total footprint, and llm-stats' head-to-head now gives it all three shared benchmarks. The thesis Laguna S 2.1 was built to demonstrate now has better demonstrations.
One claim from July does still hold. Laguna S 2.1 remains the highest-scoring Western open-weight model on Terminal-Bench 2.1, ahead of Inkling-Small (64.7), Inkling (63.8), MAI-Code-1.1-Flash (62.9), Solar Pro 4 (57.0) and Nemotron 3 Ultra (56.4). Poolside has not shipped a successor; its model release notes still end at Laguna S 2.1.
Architectural Insights: MoE Design and Agentic Fine-Tuning
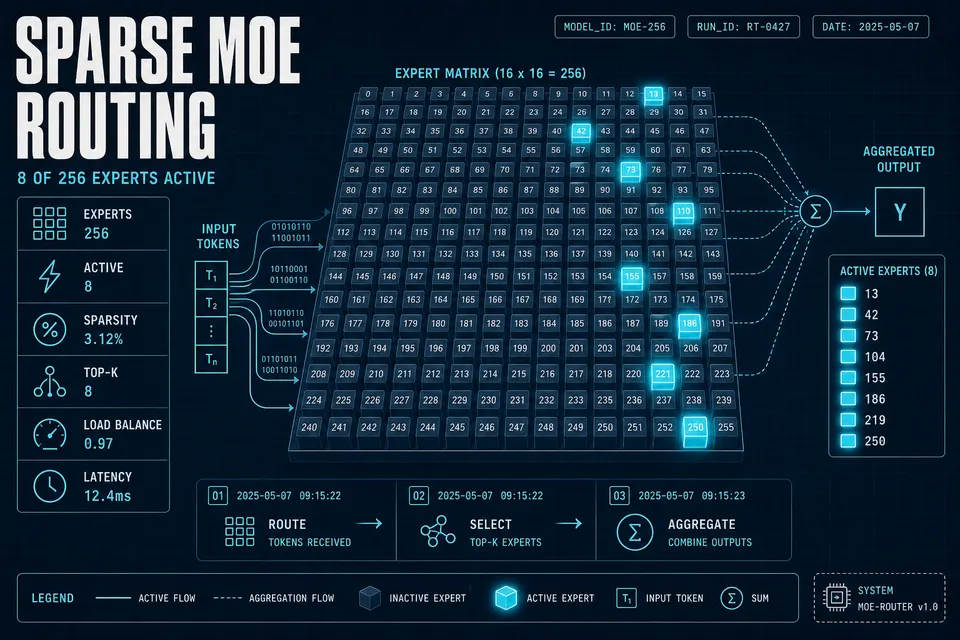
Laguna S 2.1 relies on a sparse MoE layout incorporating 256 routed experts and 1 shared expert, utilizing grouped-query attention and interleaved sliding-window layers across a native 1-million-token context window. Pre-trained in under nine weeks across a cluster of 4,096 Nvidia H200 GPUs, the model demonstrates that post-training environment exposure can outweigh raw pre-training volume.
Rather than altering the foundational dataset, developers built a post-training corpus spanning over 409,000 agentic and non-agentic environments; within that total, 83,000 setups are dedicated to terminal use cases and 168,000 target standard software engineering workflows. This process emphasized persistent verification habits—forcing the model to re-test code outputs against local test suites before finalizing changes.
B
Execute Shell Commands & Verification
Finalize Commit
Inspect Error Log & Re-examine Code
Task Description / Issue] --> B[Generate Initial Code Plan
The model operates with two explicit reasoning states: off and max, with no intermediate effort dial in between. Enabling max reasoning mode increases Terminal-Bench 2.1 performance from 60.4 to 70.2 and boosts DeepSWE v1.1 accuracy from 16.5% to 40.4%, albeit at an increased token generation footprint — on DeepSWE, a mean of ~249,000 completion tokens per trajectory with reasoning enabled versus ~99,000 without.
For autonomous tool interaction, the model issues structured JSON tool calls inside agentic frameworks:
Enterprise Security Posture: Local Hosting and Supply Chain Sovereignty
For technology leaders in regulated sectors—such as finance, healthcare, defense, and public infrastructure—sending proprietary source code through third-party SaaS APIs introduces legal compliance and intellectual property risks.
+-------------------------------------------------------------------+
| Enterprise Internal Security Perimeter |
| |
| +-------------------+ Local +-------------------------+ |
| | Engineering Work- | Inference | Laguna S 2.1 (Self- | |
| | stations / CI/CD | --------> | Hosted 118B-A8B MoE) | |
| +-------------------+ (No Data)| +-------------------------+ |
+-------------------------------------------------------------------+
 | (NO DATA EGRESS)
 v
 [ External Public Internet ]
Deploying open-weight models within an enterprise private cloud or air-gapped infrastructure eliminates data egress vulnerabilities. Source code, API keys, and internal system architectures remain strictly within corporate boundaries. Published under the OpenMDW-1.1 license, Laguna S 2.1 provides an auditable Western open-weight baseline, offering an alternative for organizations seeking to avoid reliance on proprietary APIs or foreign open-source dependencies. To address benchmark transparency concerns, the model developers released unedited execution logs detailing shell outputs, reasoning chains, and code modifications for every trial in the final evaluation set, at trajectories.poolside.ai.
Real-World Economics and Deployment Trade-Offs
Deploying Laguna S 2.1 requires understanding the hardware dynamics of Mixture-of-Experts architectures. Although only 8 billion parameters participate in computation for any given token, all 118 billion parameters must reside in fast GPU memory for real-time serving.
Quantization Precision
Weights in Memory
Recommended Hardware Target
4-bit (NVFP4 / INT4)
~72 GB
Single prosumer workstation / DGX Spark (128GB unified)
8-bit (FP8)
~121 GB
Single enterprise H200 or Dual 96GB Workstation GPUs
16-bit (BF16)
~235 GB
Multi-GPU node (2x 128GB+ accelerators)
Those figures come from Poolside's official vLLM serving recipe and cover weights only. A working DGX Spark deployment of the NVFP4 build loaded 67 GiB of weights alongside 27.11 GiB of FP8 KV cache — roughly 107 GB of the machine's 128 GB unified memory at 0.80 GPU memory utilization, enough cache for about 15 parallel requests at maximum context. The model does fit on a single 128 GB box, but with materially less headroom than a naive parameter-count calculation suggests.
Throughput on that class of hardware is modest. In a published DGX Spark run of the NVFP4 checkpoint, single-stream decoding measured 19.5 tokens per second, holding essentially flat at 19.39 tokens per second with a 262,144-token context. Pairing the model with Poolside's DFlash draft model for speculative decoding raised single-stream output to 31.15 tokens per second at a speculation depth of K=3, a 1.60x speedup; the recipe's suggested K=15 was slower at 29.06 tokens per second, because accepted length plateaus near two tokens regardless of depth. Under eight concurrent requests the same configuration reached 121.9 aggregate tokens per second against 91.0 without speculation. Teams sizing an internal deployment should plan around these measured figures.
For organizations that would rather not self-host, Poolside serves the model at $0.10 per million input tokens and $0.20 per million output tokens, which remains among the cheaper ways to run a 1-million-token-context coding model.
However, deployment comes with clear operational caveats:
Key Operational Considerations:
Grounding Under Pressure: Independent stress testing indicates that when forced to handle non-coding tasks under high ambiguity, the model can fabricate facts if its internal reasoning cutoff is triggered too early.
Tool Schema Rigidity: While highly effective in native agent environments, Laguna S 2.1 occasionally distorts complex nested JSON arguments when interfaced with non-standard third-party agent schemas.
Lack of Native Vision: The model does not include native multimodal image processing, requiring external OCR or vision preprocessing when interpreting UI design specs.
Specialization: Optimized for software engineering and mathematics, general-knowledge tasks trail broader foundation models.
Throughput Ceiling: On a single 128GB unified-memory workstation, expect roughly 20 tokens per second single-stream, or about 31 with speculative decoding—adequate for background agents, slow for interactive pair programming.
The Path Ahead for Enterprise Software Development
The release of Laguna S 2.1 marked a real shift in AI integration strategies for software development lifecycles: a model small enough to sit inside a corporate boundary that could hold its own against open-weight systems many times its size. What the weeks since have shown is that the shift was industry-wide rather than specific to one model. DeepSeek-V4.1-Flash now runs the same 8-billion active-parameter budget to a 90.6 on Terminal-Bench 2.1 against Laguna's 70.2, under an MIT license; a 27.8-billion-parameter dense Qwen model outscores Laguna on all three of their shared benchmarks at a quarter of the memory footprint.
For engineering organizations, the practical conclusion is unchanged but the shortlist is not. The choice is no longer restricted to paying high per-token API costs or accepting low-quality local code completion. But the open-weight field now turns over in weeks, and a model chosen in July on the strength of a leaderboard position will not hold that position by autumn. License terms, data sovereignty, quantized memory footprint and measured throughput on hardware the organization actually owns are the durable selection criteria; benchmark rank is not.
Correction
14 September 2026. Two claims in the original version of this article, published 22 July 2026, were not supported by any published source. Both have been corrected.
Inference throughput. The article stated that Laguna S 2.1 quantized to 4-bit NVFP4 achieved "single-stream generation speeds of up to 109 tokens per second at 256K context lengths," and that "single-user inference speeds reach up to 271 tokens per second" when paired with speculative decoding. Neither figure appears in Poolside's launch post, the Hugging Face model card, or the official vLLM serving recipe — none of which publish tokens-per-second numbers at all. The measured figures from a published DGX Spark run of the NVFP4 build are 19.5 tokens per second single-stream, 19.39 at a 262,144-token context, and 31.15 tokens per second with DFlash speculative decoding at K=3. The original numbers overstated real single-stream throughput by roughly five to nine times. The run is documented at dev.classmethod.jp/en/articles/dgx-spark-laguna-s-2-1-nvfp4/.
DeepSWE v1.1. The article stated that Laguna S 2.1's 40.4% on DeepSWE v1.1 was "significantly outperforming larger open-weight alternatives." Poolside's own launch table contradicted this on the day of publication: it listed GLM-5.2, a 753-billion-parameter open-weight model with 40 billion active, at 44.0% — above Laguna. The accurate statement is that Laguna S 2.1 scored far ahead of DeepSeek-V4-Pro-Max (9.0) and behind GLM-5.2 (44.0). As of 13 September 2026 it ranks 28th of 32 models on the public DeepSWE 1.1 board, behind five open-weight models.
Separately, the 4-bit memory footprint has been corrected from ~59 GB to ~72 GB to match Poolside's official serving recipe; ~59 GB was a naive parameter-count calculation rather than a measured or published footprint. Benchmark ranks, the SWE-Bench Multilingual framing, the description of Poolside's 409,000-environment training corpus and the competitive comparison set have all been updated to the position as of 14 September 2026.