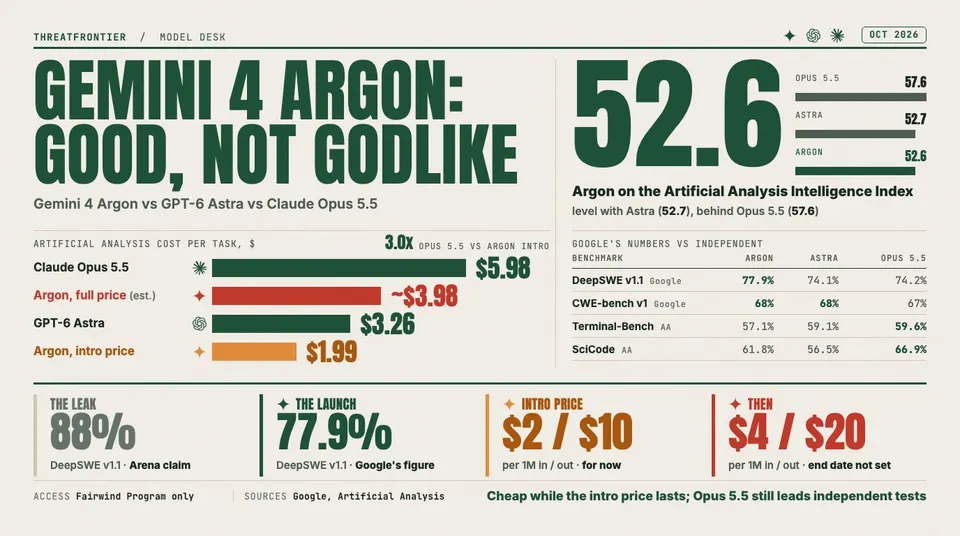
The leaked 'Gemini 4 Pro' was billed as an Astra and Opus killer. The real Gemini 4 Argon wins Google's tests, ties Astra on neutral ones, and is cheap for now.
For two weeks the story was "Gemini 4 Pro beats GPT-6 Astra and Claude." A model believed to be Google's next flagship appeared on Arena on 17 September under the name gemini-3.8-flash, and testers posted numbers that left everything else behind. On 30 September Google announced the real thing. It is called Gemini 4 Argon, not Pro. It is good, but not as good as the leak suggested, it is only cheap for now, and most people cannot use it yet.
The leak versus the launch
| Arena leak ("Gemini 4 Pro") | Gemini 4 Argon, as announced | |
|---|---|---|
| DeepSWE v1.1 | 88% | 77.9% |
| Output limit | 256K tokens | 1M tokens (up from 64K) |
| Input context | "10 million tokens" | not specified |
| Price per 1M tokens, in / out | $2.25 / $11.25 | $2 / $10 introductory, then $4 / $20 |
| Availability | Arena, anonymously | Trusted cyber defenders only |
The leaked coding score was about ten points too high, and the 10-million-token context does not appear anywhere in Google's announcement. The leaked price was close. Unverified Arena screenshots are a poor guide to a release, and this one was off on the numbers that drew the most attention.
What Google claims
Google published 18 benchmarks. By VentureBeat's count, Argon leads outright on 12, ties on one, and trails GPT-6 Astra on three and Claude Opus 5.5 on two. The headline results:
| Benchmark | Gemini 4 Argon | GPT-6 Astra | Claude Opus 5.5 |
|---|---|---|---|
| DeepSWE v1.1 (software engineering) | 77.9% | 74.1% | 74.2% |
| AutomationBench (business tasks) | 51.3% | 41.4% | 42.5% |
| Vals Finance Agent v2 | 65.4% | 53.5% | 58.6% |
| Harvey Legal Agent Benchmark | 19.6% | 5.4% | 3.8% |
| GraphWalks (long-context reasoning) | 84.2% | 71.8% | 66.8% |
| LVBench (long video) | 91.7% | 87.5% | 83.7% |
| CWE-bench v1 (vulnerability fixing) | 68% (tie) | 68% (tie) | 67% |
These are Google's chosen benchmarks, run on Google's settings. The coding lead is real but small, about 3.7 points on DeepSWE. The gaps in legal, finance and long-context work are much larger.
What independent testing says
Artificial Analysis ran Argon through its own index on launch day, and the picture changes.
| Artificial Analysis | Gemini 4 Argon (High) | GPT-6 Astra (Max) | Claude Opus 5.5 (Max) |
|---|---|---|---|
| Intelligence Index | 52.6 | 52.7 | 57.6 |
| Terminal-Bench (terminal coding) | 57.1% | 59.1% | 59.6% |
| Humanity's Last Exam | 57.1% | 54.7% | 61.4% |
| GDPval-AA (work tasks, 44 jobs; Elo) | 1,611 | 1,542 | 1,846 |
| SciCode | 61.8% | 56.5% | 66.9% |
| Cost to run one task | $1.99 | $3.26 | $5.98 |
On a neutral harness, Argon ties Astra and trails Opus 5.5 by about five points. Its advantage is cost: Artificial Analysis says Astra-level performance costs about 39% less per task on Argon, and Opus 5.5's extra five points cost three times as much.
The price comes with a deadline
Argon's introductory rate is $2 input and $10 output per million tokens. That is a fifth of Astra's $10 / $50 list price and half of Opus 5.5's $4 / $20. Cached input is 95% off.
The regular price, once the introductory period ends, is $4 / $20, exactly what Opus 5.5 costs. Artificial Analysis's $1.99 per task was measured at the introductory rate. Every token price doubles, so by our arithmetic the same workload would cost about $3.98 per task at full price. That is more than Astra's $3.26 and still below Opus 5.5's $5.98. Google has not said when the introductory period ends.
You probably cannot use it yet
Argon is rolling out first to "trusted cyber defenders" through Google's Fairwind Program, and Google is taking part in the US government's voluntary pre-release testing process. Paid API customers and Google AI Ultra subscribers are next, with no date beyond "as soon as possible." Unless you are in Fairwind, any decision about Argon is a decision about a model you cannot call.
Why the security launch matters
Google is launching Argon as a cyber-defence model first, and the security claims are the most concrete part of the announcement:
- Vulnerability repair: 68% on CWE-bench v1, tied with GPT-6 Astra and one point ahead of Opus 5.5. That is level with the best, not ahead of it.
- Prompt injection: Gray Swan's indirect prompt-injection test measured a 0.7% attack success rate for Argon, against 1.0% for Opus 5.5 and Fable 5.1. Google calls Argon its "most resilient model yet" against indirect injection.
- Field results: Google says Wiz used Argon to find a critical flaw exposing personal data in healthcare software used by hospitals worldwide, and that Argon mapped an attack surface better than 3.8 Flash Cyber.
- Guardrails: monitors watch Argon's reasoning and actions and can stop execution. Its safeguards specifically target cyber and CBRN misuse.
For a security team the useful takeaway is narrower than the marketing. Argon matches the best on fixing vulnerabilities and slightly improves on injection resistance. A 0.7% attack success rate still means injection gets through sometimes. Agents that read untrusted content still need sandboxing and least-privilege tools whichever model runs them.
So, is it good?
Yes, with conditions.
- Coding agents: Argon is roughly level with Astra and behind Opus 5.5 on independent tests. It is cheaper than both while the introductory price lasts. At full price it costs the same per token as Opus 5.5 and scores lower.
- Legal, finance and long-context work: this is where Google's own lead is largest. It is worth testing as soon as you get access, but confirm the results on your own documents first.
- Security teams: if you can get into Fairwind, it is a strong vulnerability-repair model with the best published injection score of the three. If not, Astra matches it on CWE-bench today.
- "Gemini 4 Pro" as the leaks described it does not exist. Benchmark Argon on your own workload before you switch.
Sources
- Google, "Gemini 4 Argon: our next era of frontier intelligence", 30 Sep 2026
- VentureBeat, "Google unveils Gemini 4 Argon, retaking benchmark lead over OpenAI and Anthropic — but in limited release"
- Trending Topics, Artificial Analysis results: "Gemini 4 Matches GPT-6 Astra but Trails Opus 5.5"
- Help Net Security, "Google says Gemini 4 Argon can find and patch critical software flaws", 1 Oct 2026
- TechBriefly, "Leaked Gemini 4 Pro benchmarks show it beating GPT-6 Astra and Claude", 21 Sep 2026